h.e. boukhalfa
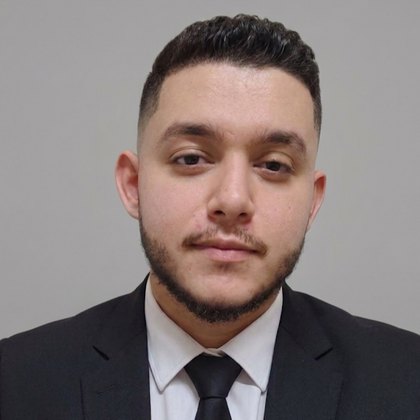
Portrait of Houssam Eddine BoukhalfaParis-Saclay, France

Houssam Eddine Boukhalfa

Machine learning researcher · M2 Data Science, Université Paris-Saclay

I train language models against checkers that can prove an answer right or wrong, and study what the models actually learn from them.

Looking for a 6-month research internship from late March 2027

Research

What a model learns when we train it

I'm finishing an M2 in Data Science (TRIED) at Université Paris-Saclay, co-accredited with Institut Polytechnique de Paris. Before that I completed a five-year engineering degree and a Master 2 in Artificial Intelligence and Data Science at ENSIA in Algiers.

With the University of Birmingham, we showed that supervised fine-tuning can teach a language model the format of correct answers without the reasoning behind them, and that reinforcement learning against symbolic verifiers repairs it. I also built LLM world models that predict how a planning environment changes after each action, and evaluated how they generalise to domains they have never seen.

On the engineering side, I led the AI team at Nojoom.AI that trained Arabic language models up to 42 billion parameters, and I care about making training and inference efficient, from data selection down to GPU kernels.

  • RL with verifiable rewards
  • LLM reasoning
  • World models & planning
  • LLM agents & tool use
  • Efficient training & inference
  • Arabic & multilingual LLMs

News

Recent updates

  • Our EMNLP 2026 Findings paper on counterexample generation is on arXiv, with the SymCE dataset, verifiers and code.
  • Started the M2 Data Science (TRIED) at Université Paris-Saclay.
  • Graduated from ENSIA with an engineering degree and a Master 2 in AI and Data Science, after defending my final-year thesis (defense video).
  • First-author paper on Arabic children's story generation at the Muslims in ML Workshop, NeurIPS 2025.
  • Joined Nojoom.AI as R&D Engineer and AI Team Lead, and LIX (École Polytechnique) as a research intern.

Results

Selected results

Imitation hurts, reinforcement repairs

EMNLP 2026 Findings
True-theorem recognition · Qwen3-4B · scale 0–1
  • Base model0.27
  • SFT0.00✗
  • RLVR (GRPO)0.66✓

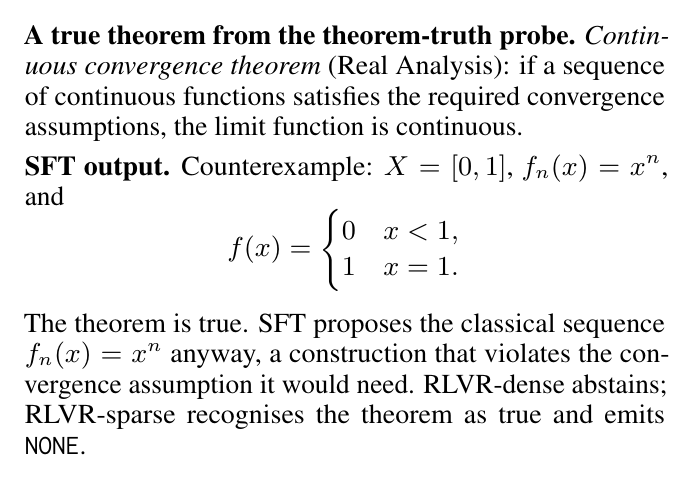
Supervised fine-tuning learned the answer format but lost the logic; RL with verifier rewards brought it back. The 4B model beat every evaluated 7B open math specialist. Paper

Figure 1 of the paper: on a true theorem about continuous convergence, the SFT model still proposes the counterexample f_n(x) = x^n, which violates the theorem's assumptions; the RLVR-sparse model recognises the theorem as true.
Figure 1 of the paper. The theorem is true, yet the SFT model still fabricates a counterexample; the model trained with a sparse verifier reward recognises it as true.

LLM world model for planning

Final-year thesis
Next-state accuracy (%) · PDDL environments · scale 0–100

Unseen domains

  • SFT86.7
  • CE-RLVR96.3✓

Seen domains

  • SFT84.7
  • CE-RLVR89.2✓

The gain came from penalising repeated errors with a memory of past counterexamples, not from denser reward shaping. Thesis

AQL-42B, an Arabic LLM

Nojoom.AI
Open Arabic LLM Leaderboard v2 · average of 7 benchmarks · scale 0–100
  • Base model50.48
  • AQL-42B79.17✓

Mixture-of-experts model depth-extended from Qwen3-30B-A3B (48 → 66 layers, 4.5B active), with an Arabic tokenizer using 28% fewer tokens and 275B tokens of continued pretraining.

Publications

Papers

  1. Counterexample Generation via Per-Theorem Symbolic Verifiers: When Imitation Hurts and Reinforcement Repairs

    O. F. Zouak, H. E. Boukhalfa, S. Lakehal, S. Katiyar, S. Nefti-Meziani

    EMNLP 2026 (Findings), Budapest

    My role: set up the training pipeline and trained the models (SFT, then GRPO-based RLVR).

    BibTeX
    @inproceedings{zouak2026counterexample,
      title     = {Counterexample Generation via Per-Theorem Symbolic Verifiers:
                   When Imitation Hurts and Reinforcement Repairs},
      author    = {Zouak, Omar Farouk and Boukhalfa, Houssam Eddine and
                   Lakehal, Soumaya and Katiyar, Shiv and Nefti-Meziani, Samia},
      booktitle = {Findings of the Association for Computational Linguistics: EMNLP 2026},
      year      = {2026},
      note      = {arXiv:2610.02444}
    }
  2. Crafting Culturally Aligned Narratives: Large Language Models for Arabic Children's Story Generation

    H. E. Boukhalfa, S. Mani, L. Said Chikh

    Muslims in ML Workshop, NeurIPS 2025, San Diego

    BibTeX
    @inproceedings{boukhalfa2025crafting,
      title     = {Crafting Culturally Aligned Narratives: Large Language Models
                   for Arabic Children's Story Generation},
      author    = {Boukhalfa, Houssam Eddine and Mani, S. and Said Chikh, L.},
      booktitle = {Muslims in ML Workshop at NeurIPS 2025},
      year      = {2025}
    }

In preparation: a paper on detecting information influence operations on TikTok, from my work at LIX, École Polytechnique.

Thesis

CE-RLVR: Internalizing Symbolic Reasoning in LLMs through Counterexample-Guided RLVR

Final-year thesis on counterexample-guided reinforcement learning with verifiable rewards, at ENSIA in collaboration with the University of Birmingham, supervised by Prof. Samia Nefti-Meziani, Dr Shiv Ashutosh Katiyar and Dr Soumaya Lakehal.

Experience

Research and engineering

  1. R&D Engineer, AI Team Lead

    Sept 2025 – May 2026 Nojoom.AI
    • Led the AI team that trained, evaluated and deployed the company's Arabic LLMs (multi-GPU training with DeepSpeed, deployment on Google Cloud).
    • AQL-42B: depth-extended MoE model, Arabic tokenizer with 28% fewer tokens, 275B-token continued pretraining; 79.17 vs 50.48 on the Open Arabic LLM Leaderboard v2.
    • AQL-Lite: a five-stage data filtering and selection pipeline (885B → 215B tokens) and structured parameter-efficient training on Gemma 3 12B that kept 94% of the gains of full continued pretraining in 52% of the training time.
  2. End-of-studies research project (remote)

    July 2025 – June 2026 ENSIA & University of Birmingham
    • Counterexample-guided RL with verifiable rewards for LLM reasoning, using symbolic verifiers as rewards.
    • Owned the world-model pipeline end to end: PDDL data, SFT, GRPO-based CE-RLVR training and evaluation on Qwen3-4B.
    • Set up the training pipeline for the EMNLP 2026 Findings paper.
  3. Research Intern (remote)

    Sept 2025 – June 2026 LIX, École Polytechnique (IP Paris)
    • Built an end-to-end multimodal pipeline to detect information influence operations on TikTok: video extraction, transcription, translation, text and video analysis.
    • Used a vision-language model to check what video descriptions claim against what the videos show, and analysed engagement in the 2024 Romanian presidential election. Supervised by Dr Oana Goga and Gabriel Ben Zenou (Inria Paris-Saclay).
  4. Teaching Assistant

    2025 Limitless Learning
    • Practical sessions on deep learning, Transformers, LoRA and RAG.
  5. AI/ML Intern

    2024 Think Touch Solution
    • Accelerated LLM inference on an HPC system, parallelised in C/C++ with MPI and OpenMP/pthreads.
  6. AI/ML Intern

    2024 Cosider Agrico
    • Retrieval-augmented question answering over the company's internal documents.

Education

Degrees

  1. M2 Data Science (TRIED)

    2026 – 2027 Université Paris-Saclay, co-accredited with Institut Polytechnique de Paris
  2. Engineering Degree and Master 2 in AI and Data Science

    2021 – 2026 National Higher School of Artificial Intelligence (ENSIA), Algiers · final-year project 17.5/20

Projects

Things I've built

  1. Quality Takeoffs

    2025 – present

    AI agents and computer vision read technical drawings, extract and measure their elements (legend tables, fixtures, measurements) and write the takeoff report.

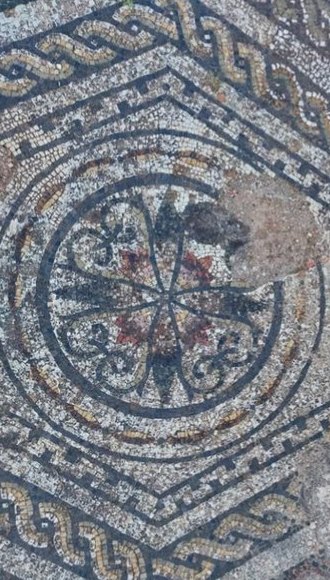
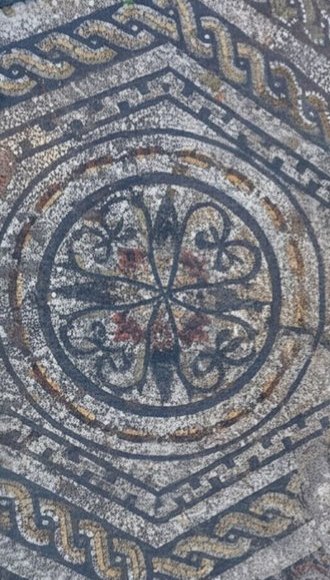
  2. Roman mosaic restoration with GANs

    2025 · Stanford University, supervised by Dr Mourad Bouache

    A GAN with a Vision Transformer and contextual attention that restores damaged Roman mosaics.

    Roman mosaic with a large damaged area on the right of its central medallion
    Damaged original
    The same mosaic after restoration by the model, with the damaged area filled in to match the surrounding pattern
    Restored by the model
  3. Reinforcement learning for autonomous racing

    2025

    A DQN driving agent in simulation, from environment modelling and sensor inputs to reward design and robustness analysis.

Skills

Tools and methods

Post-training
SFT, RL with verifiable rewards (GRPO), reward and verifier design, PEFT (LoRA, RS-LoRA), distillation, quantization
Training at scale
DeepSpeed multi-GPU training, continued pretraining, MoE depth upscaling, data filtering and selection
Agents
LangChain, LangGraph, MCP tool calling, RAG
Performance
Triton and CUDA C++ kernels, vLLM, MPI, OpenMP
Programming
Python, C/C++, SQL · PyTorch, Hugging Face (Transformers, TRL, PEFT), Unsloth, Google Cloud
Languages
Arabic (native), English (C1), French (C1)

Also: co-founder of the ENSIA Tech Community Club, winner of three national AI hackathons, and supervisor of the student teams that organised the Algerian AI Council (Dec 2024) and the AI for Africa conference series (Dec 2023).